Scalable AI for CMC: How To Measure Whether It Can Be Trusted
"We have an AI assistant that answers questions about our processes and products. Should we trust it?"
We hear some version of that question every day. It's a fair one, and the honest answer starts with how these systems are judged.
Many of those pilots follow a familiar arc. It starts with a demo. Someone asks for information, and the answer comes back in seconds, every time. The team sees instant results, the executive sponsor gets excited, and the budget gets approved. Then the project stalls. It stays in proof of concept, or it ships for one narrow use case, because no one can show how the assistant performs on the questions that matter. That gap surfaces the first time someone asks the assistant a real question.
That pattern shaped how we approached our own AI: we set out to build it with measurement in mind from the start.
Lost in Transfer
Let’s talk about Caroline, a manufacturing science and technology (MSAT) lead preparing to transfer a tablet process from development into commercial manufacturing at a new site. Before scale-up, she asks her company's AI assistant: "What development work supports this process parameter range?" She needs the range, and she also needs every study, risk assessment, and report that explains why it sits where it does, because those records tell her what is safe to adjust at scale and what puts dissolution at risk.
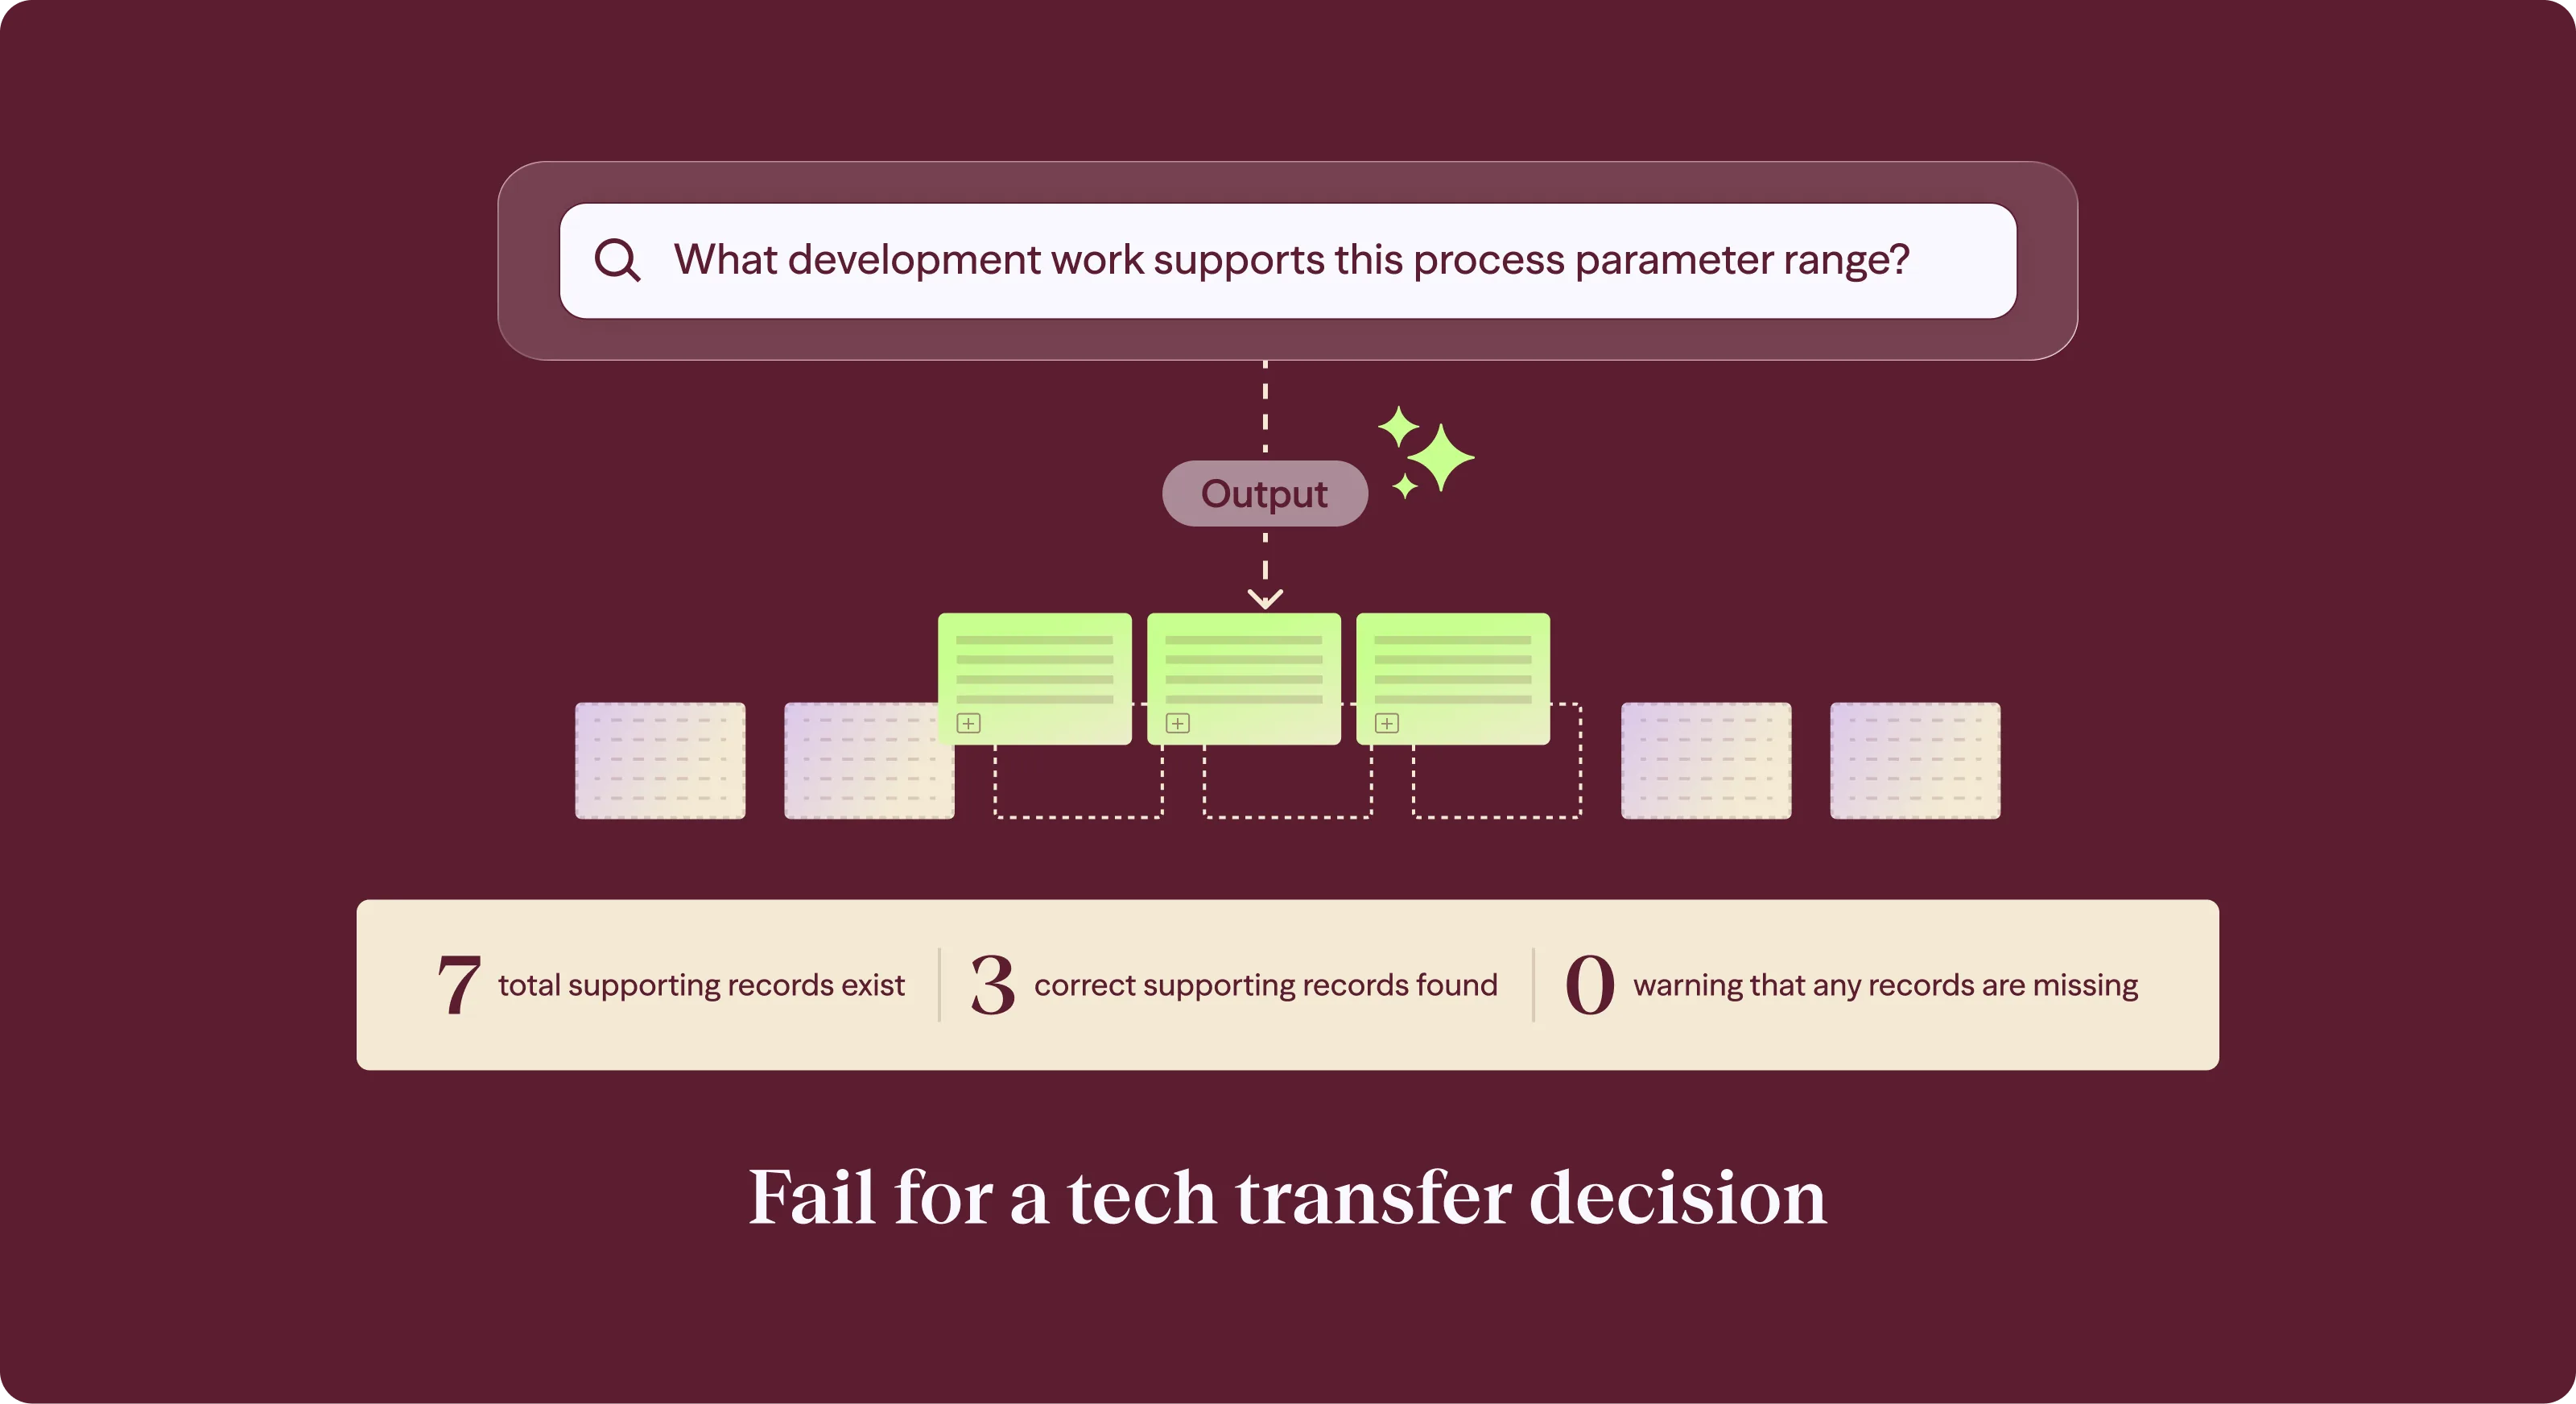
The response comes back quickly and reads as complete. Seven records support that range, and the list has three.
Nothing on the screen says anything is missing. There is no count to check against and no warning. One of the four missing records is the design of experiments showing dissolution failing above the upper limit, and the scientists who ran it no longer work in her department. The receiving site now plans to scale up on a partial picture of the process. In CMC, a wrong answer that looks right is worse than no answer at all.
A Data Whodunit
The obvious suspect is the model, but the model is only part of the story.
Most AI performance claims describe the model: how it scores on scientific reasoning benchmarks, how well it answers general questions. They say little about whether a system can do the specific work CMC requires. A model can score well and still miss a process parameter, lose the link between a unit operation and its steps, or return three correct studies when seven exist. In CMC, correct and complete are different measures. So are accurate and trustworthy.
The deeper cause sits in the data. Anthropic ran into the same wall studying why AI agents for biology are advancing more slowly than expected, and described it this way: "Using AI agents to navigate biological data infrastructure is like driving through an old city that was designed before cars: the infrastructure may be beautiful and even thoughtful, but it's full of narrow, winding streets that are difficult for modern vehicles to navigate."
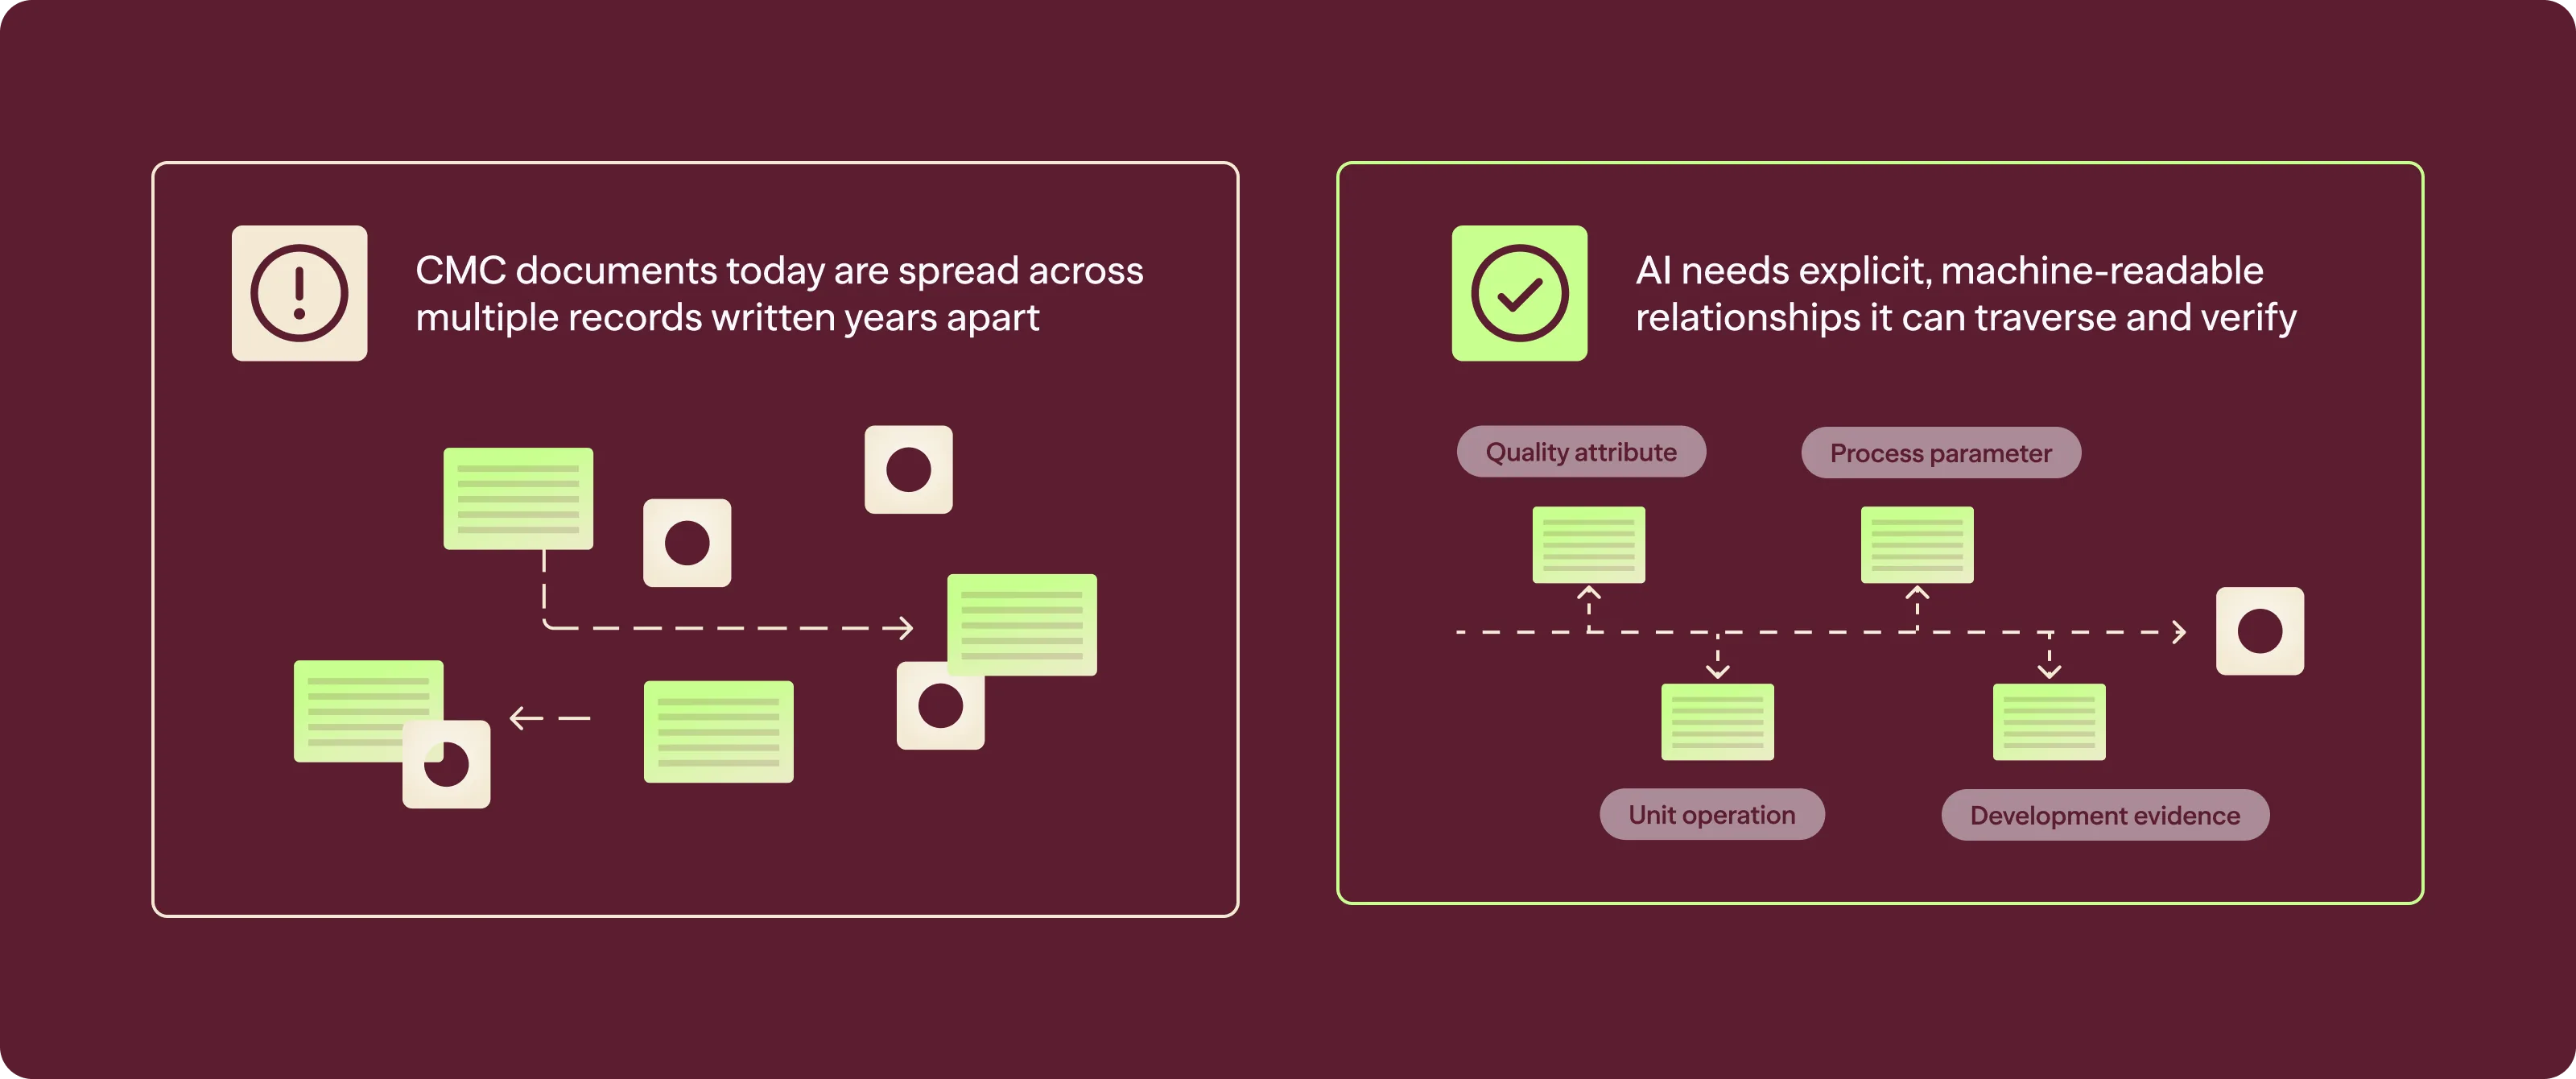
CMC has a similar city planning problem. Process knowledge builds up over a product's whole life in development reports, risk assessments, batch records, and change controls, written by different teams in different systems, years apart. The development teams’ understanding lives in narrative text written for people to read, and the link between the quality attribute, the process parameter, the unit operation, and the study that justifies it was never recorded as a relationship. When the process moves to manufacturing, the documents travel with it and the connections stay behind.
A common view holds that the next generation of frontier models will close this gap, and models are improving. They iterate: they ask, read, refine, and recover more than single-shot retrieval ever could. They will find more of the seven. But two things stay out of their reach. A model cannot certify that it found everything, and it cannot tell you whether 85% is acceptable or catastrophic for a tech transfer decision.
Our own research points the same way. We gave models the same CMC extraction task three ways. In the first, the entire document goes into a single prompt that is asked to return everything. In the second, the prompt adds CMC context and domain-specific instructions. In the third, the work is decomposed into operation-specific tasks, with materials, equipment, unit operations, steps, and process parameters each extracted on their own. The structured approach performed best.
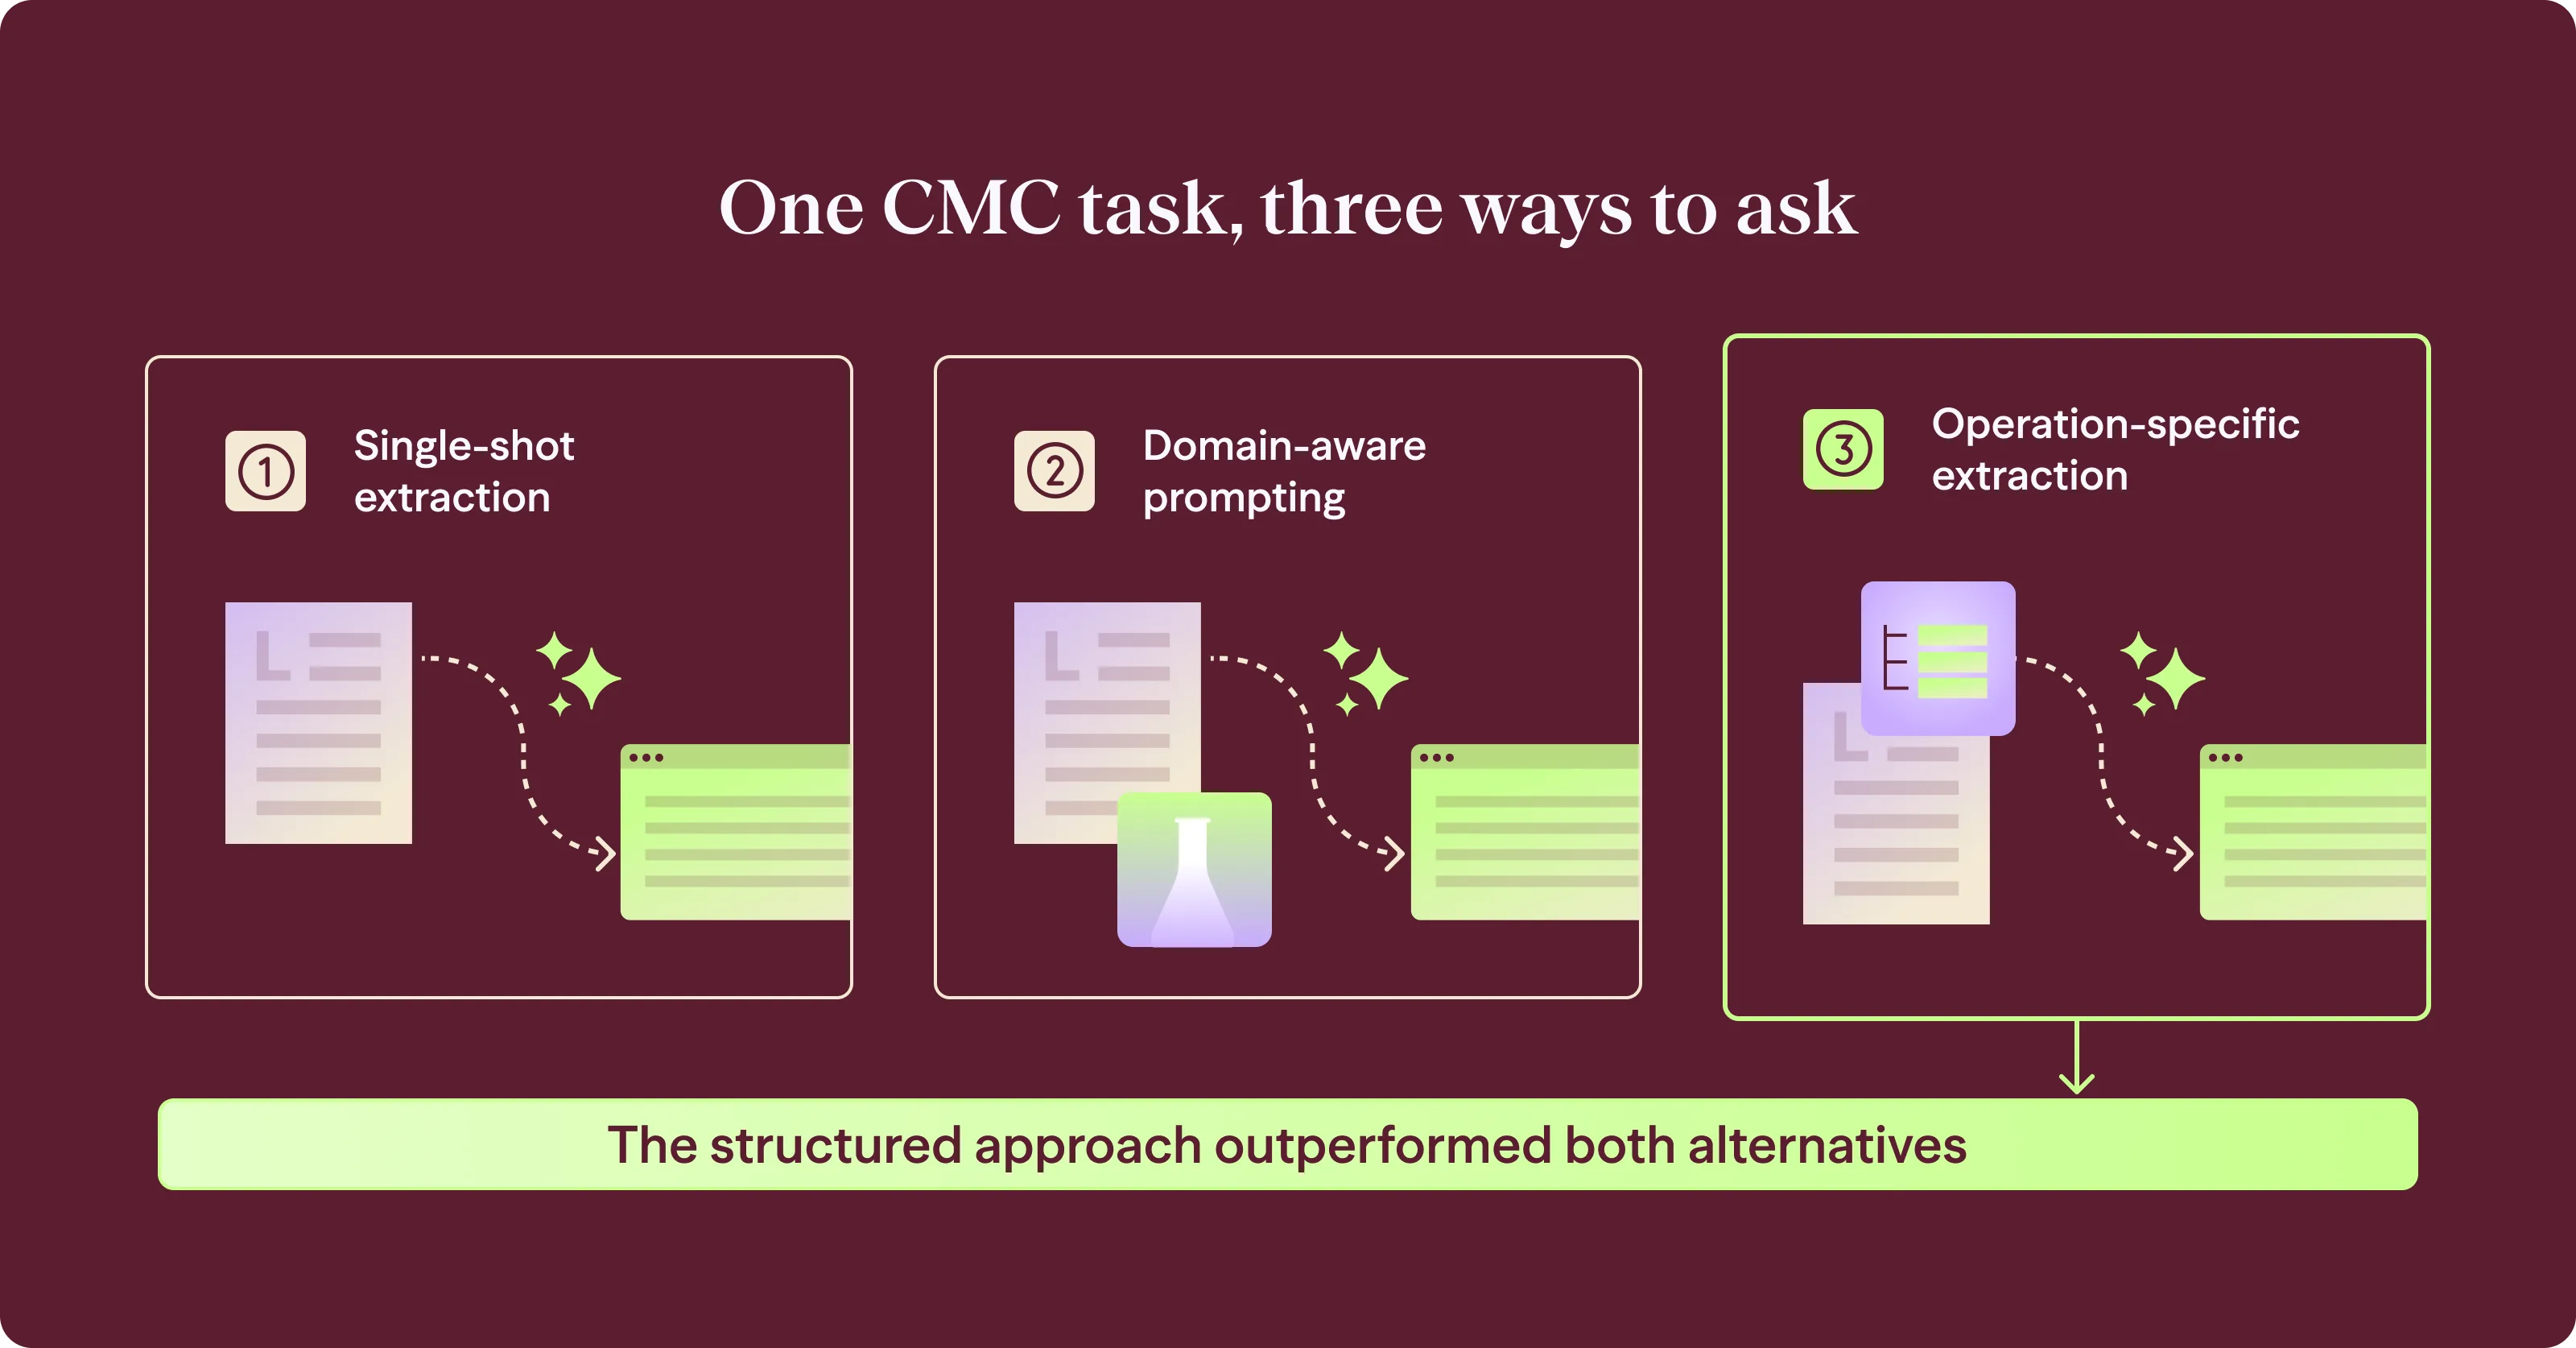
The task and the documents stayed the same in all three approaches; what changed was how the work was structured. Breaking extraction into defined pieces, each graded on its own, outperformed a single prompt asked to find everything at once, which is exactly the setup that returns three studies and stops.
The same Anthropic research put numbers on this pattern. Its benchmark, VirBench, includes 120 realistic viral sequence queries spanning 40 pathogens, with manually verified ground truth. Working on their own, leading scientific research agents reached mean accuracies between 16.9% and 91.3%. When the researchers gave the same agents a virus, a deterministic retrieval layer that turns a complex, browser-based workflow into a reproducible interface, accuracy rose above 90% for every agent and peaked at 99.7%. The agents were identical in both conditions, and the researchers attributed most of the variation in performance to shortcomings in the data infrastructure.
Taken together, the two results point to one conclusion. The model sets a ceiling, and the structure of the knowledge it works with decides how close an answer gets to that ceiling. Structure also makes an answer checkable. When CMC knowledge is recorded as connected data, with each process parameter linked to its unit operation, the quality attributes it affects, and the records that justify its range, a system knows how many records it should return. An answer of three can be checked against the seven that exist, and the gap is visible. Narrative documents offer no count to check against, which is exactly what Caroline was missing.
The approach that holds up uses AI to turn documents into structured, connected data, then reasons over that structure. Structure is where the question "Can I trust this?" gets answered, and it's where QbDVision started.
Structured knowledge is also reusable. The connected data an AI system checks today can support the next tech transfer and feed a regulatory submission, and regulators are moving in that direction. Picture a future where AI is part of every CMC workflow: it is hard to imagine teams still writing narrative documents for machines to decode. ICH's draft M4Q(R2) guideline, which revises the quality section of the Common Technical Document, calls for submissions in a structured format with enough granularity to support digitalization and knowledge management across the product lifecycle.
Credibility Measured Against What?
If smarter models can't settle the question, health authority guidance will. The FDA's January 2025 draft guidance on AI for regulatory decision-making frames trust as credibility: evidence that a model performs well enough for a defined context of use. It asks sponsors to describe the performance metrics used to evaluate a model, to "specify how data independence was achieved between development (training and tuning data) and test data," and to document the model's limitations. The EMA's 2024 reflection paper on AI across the medicinal product lifecycle takes a similar risk-based view, names process design and scale-up among the manufacturing uses it expects to grow, and holds marketing authorization applicants and holders responsible for ensuring that the algorithms, models, datasets, and data processing pipelines they use are fit for purpose.
That puts the burden of proof on the company using the AI: it needs evidence that the system meets its intended use. A strong demo shows that a system can answer a question. Fitness for purpose requires evidence of how it performs across the full range of questions its intended use will bring, and that is the evidence a pilot built on a demo often lacks when it is time to scale. Data specialists point the same way. IntuitionLabs' benchmark analysis of pharma document AI found typical accuracy of 80 to 95% on mixed pharma documents and concluded that "custom domain-aware pipelines are essential."
Two words in this conversation often get blurred. Validation, in the pharma sense, is the documented demonstration that a computerized system is fit for its intended use under GxP. Benchmarking, in the AI sense, measures how a model performs against a reference set of known answers. The two are connected: benchmarking produces much of the evidence that a credibility assessment and a validation package depend on. They answer different questions, and a strong benchmark score is one input to the decision to rely on a system. We cover how they fit together in AI Credibility in CMC.
The direction is clear: generic benchmarks cannot show whether AI is credible for a specific CMC use. What the industry still lacks is a widely adopted standard for what CMC-specific measurement looks like.
So the practical questions stay open. A system reports 90% accuracy on process parameters: accuracy against clean data, or against the messy documents your sites actually produce? A system links 8 of 10 studies to the right parameter: did it miss any, and is 80% good enough for this use? And for Caroline the MSAT lead: how do you know a list is complete when nobody holds the complete list?
A credibility framework defines what good looks like for a specific use. Measurement shows whether a system meets that definition. Both need to be in place before anyone can answer "Can I trust it?"
How Caroline Would Have Known
Start by trading "Is it accurate?" for a better question: "Can I trust it for this specific job?" In CMC, AI does two different jobs, and each fails in its own way, so we measure them on two tracks.
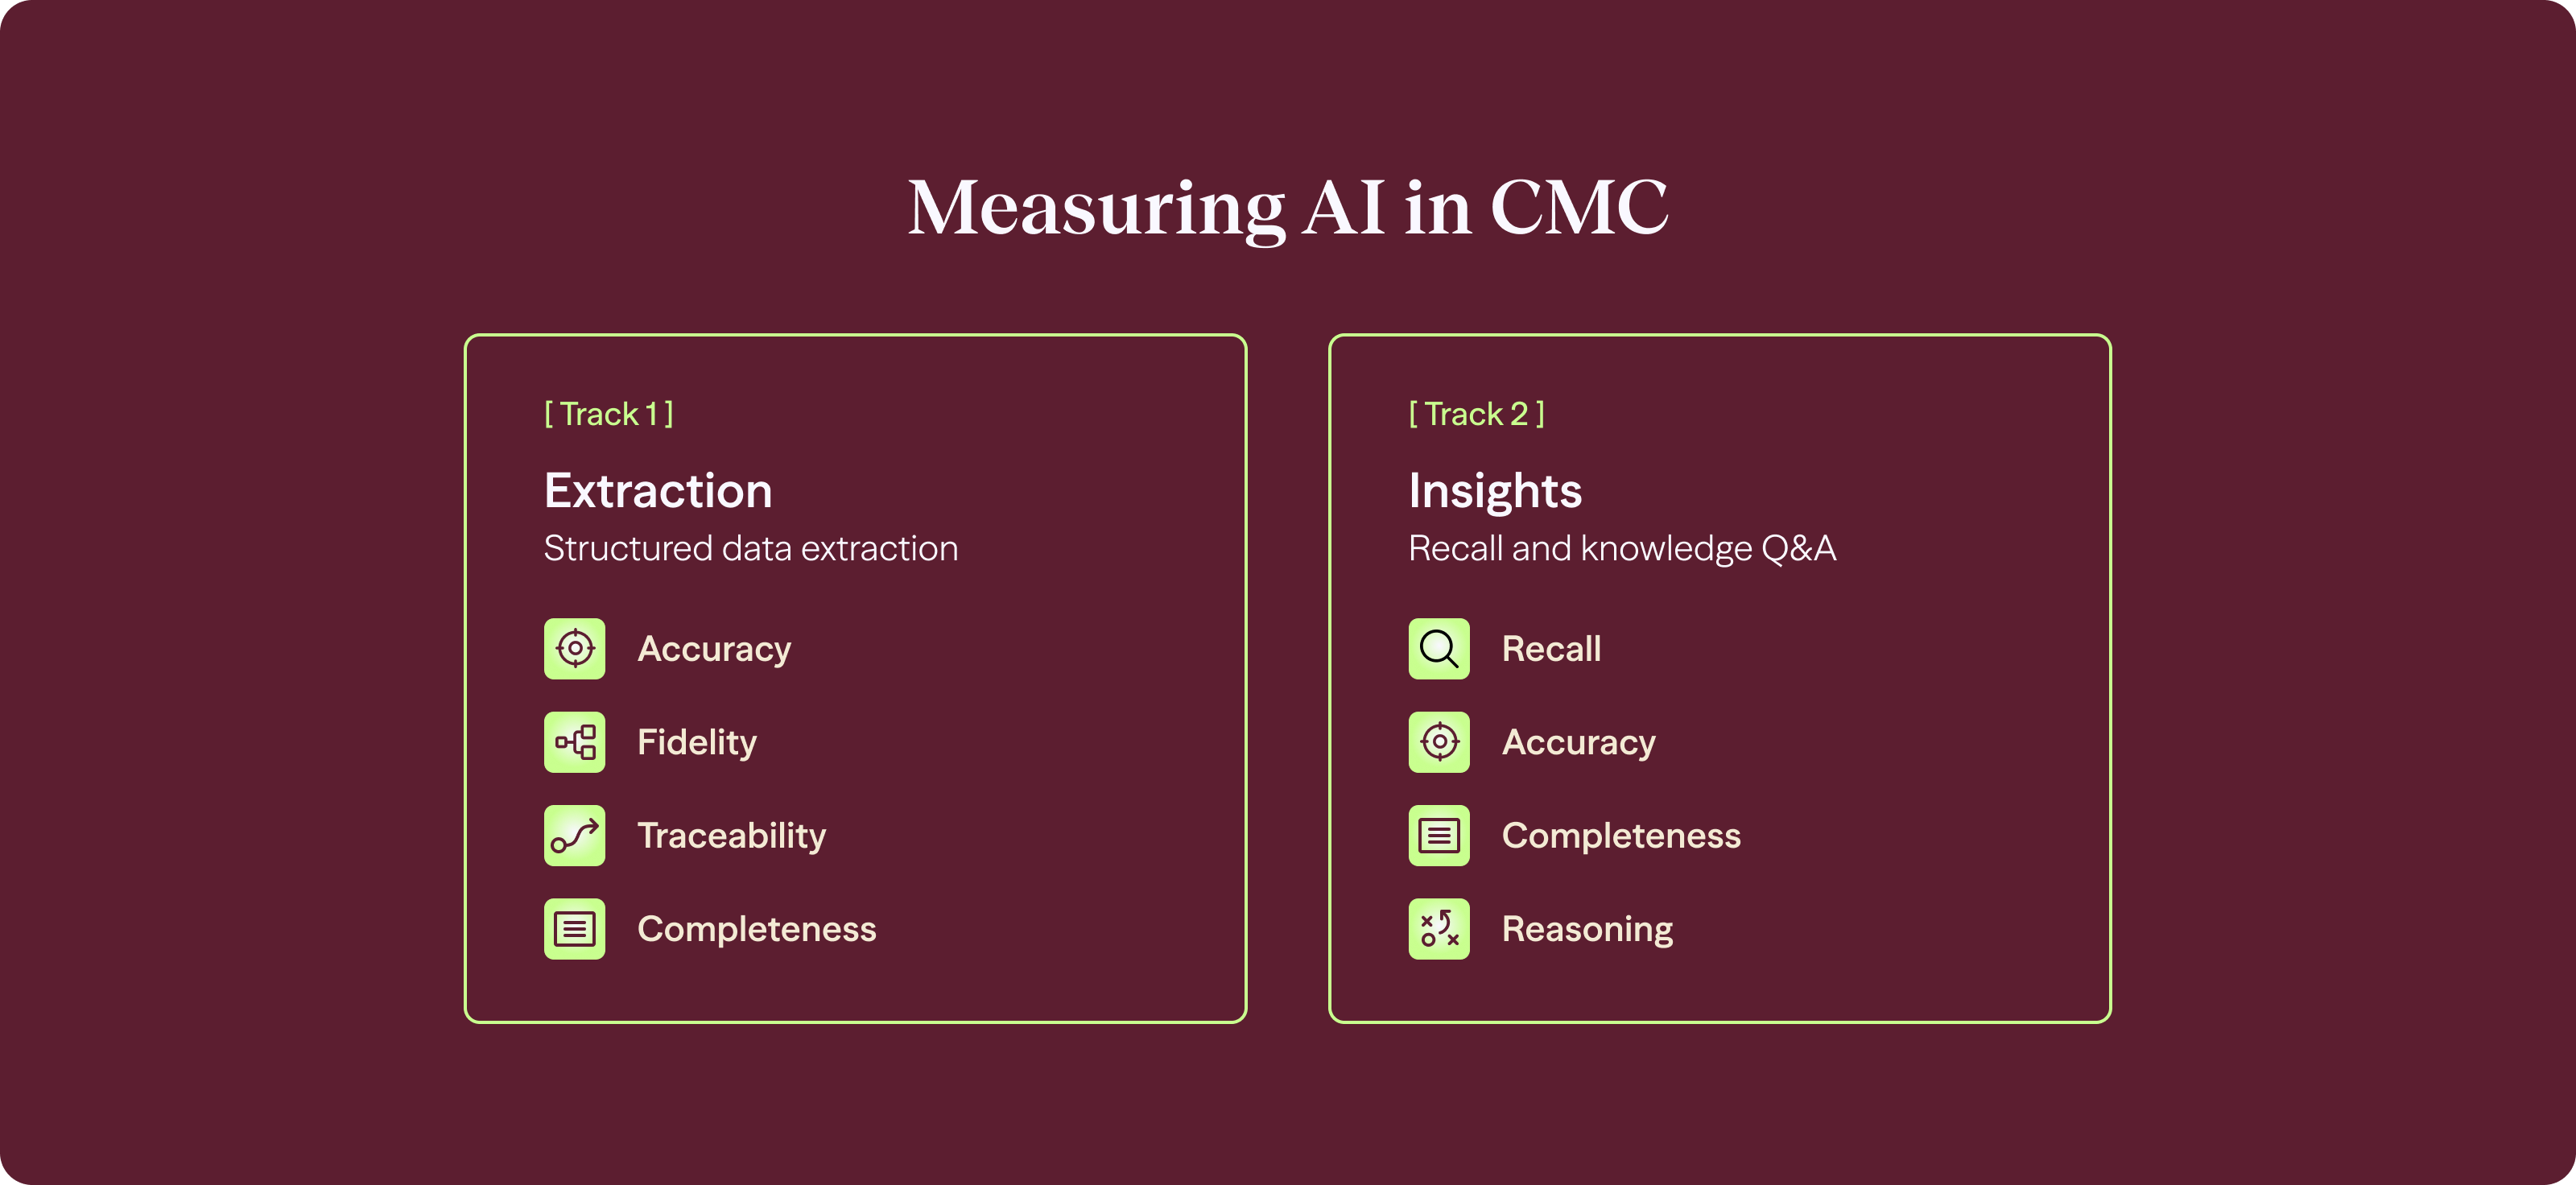
Extraction is the first job: the AI turns the content of development and manufacturing documents into structured, connected data. It is measured on four criteria.
Accuracy: each extracted value matches the source document, including units.
Fidelity: each value keeps its context, so a 1000 L batch size that belongs to Process A variant 2 stays attached to that variant and only that variant.
Traceability: every value leads back to its source document for audit.
Completeness: every value the document contains is captured.
A system can extract process parameters at 92% accuracy and still fall short on fidelity and traceability, which is why those two carry the most weight here. A system at 88% accuracy with complete traceability can be the stronger choice over one at 95% with questionable sources, because health authorities expect every value to trace to its source.
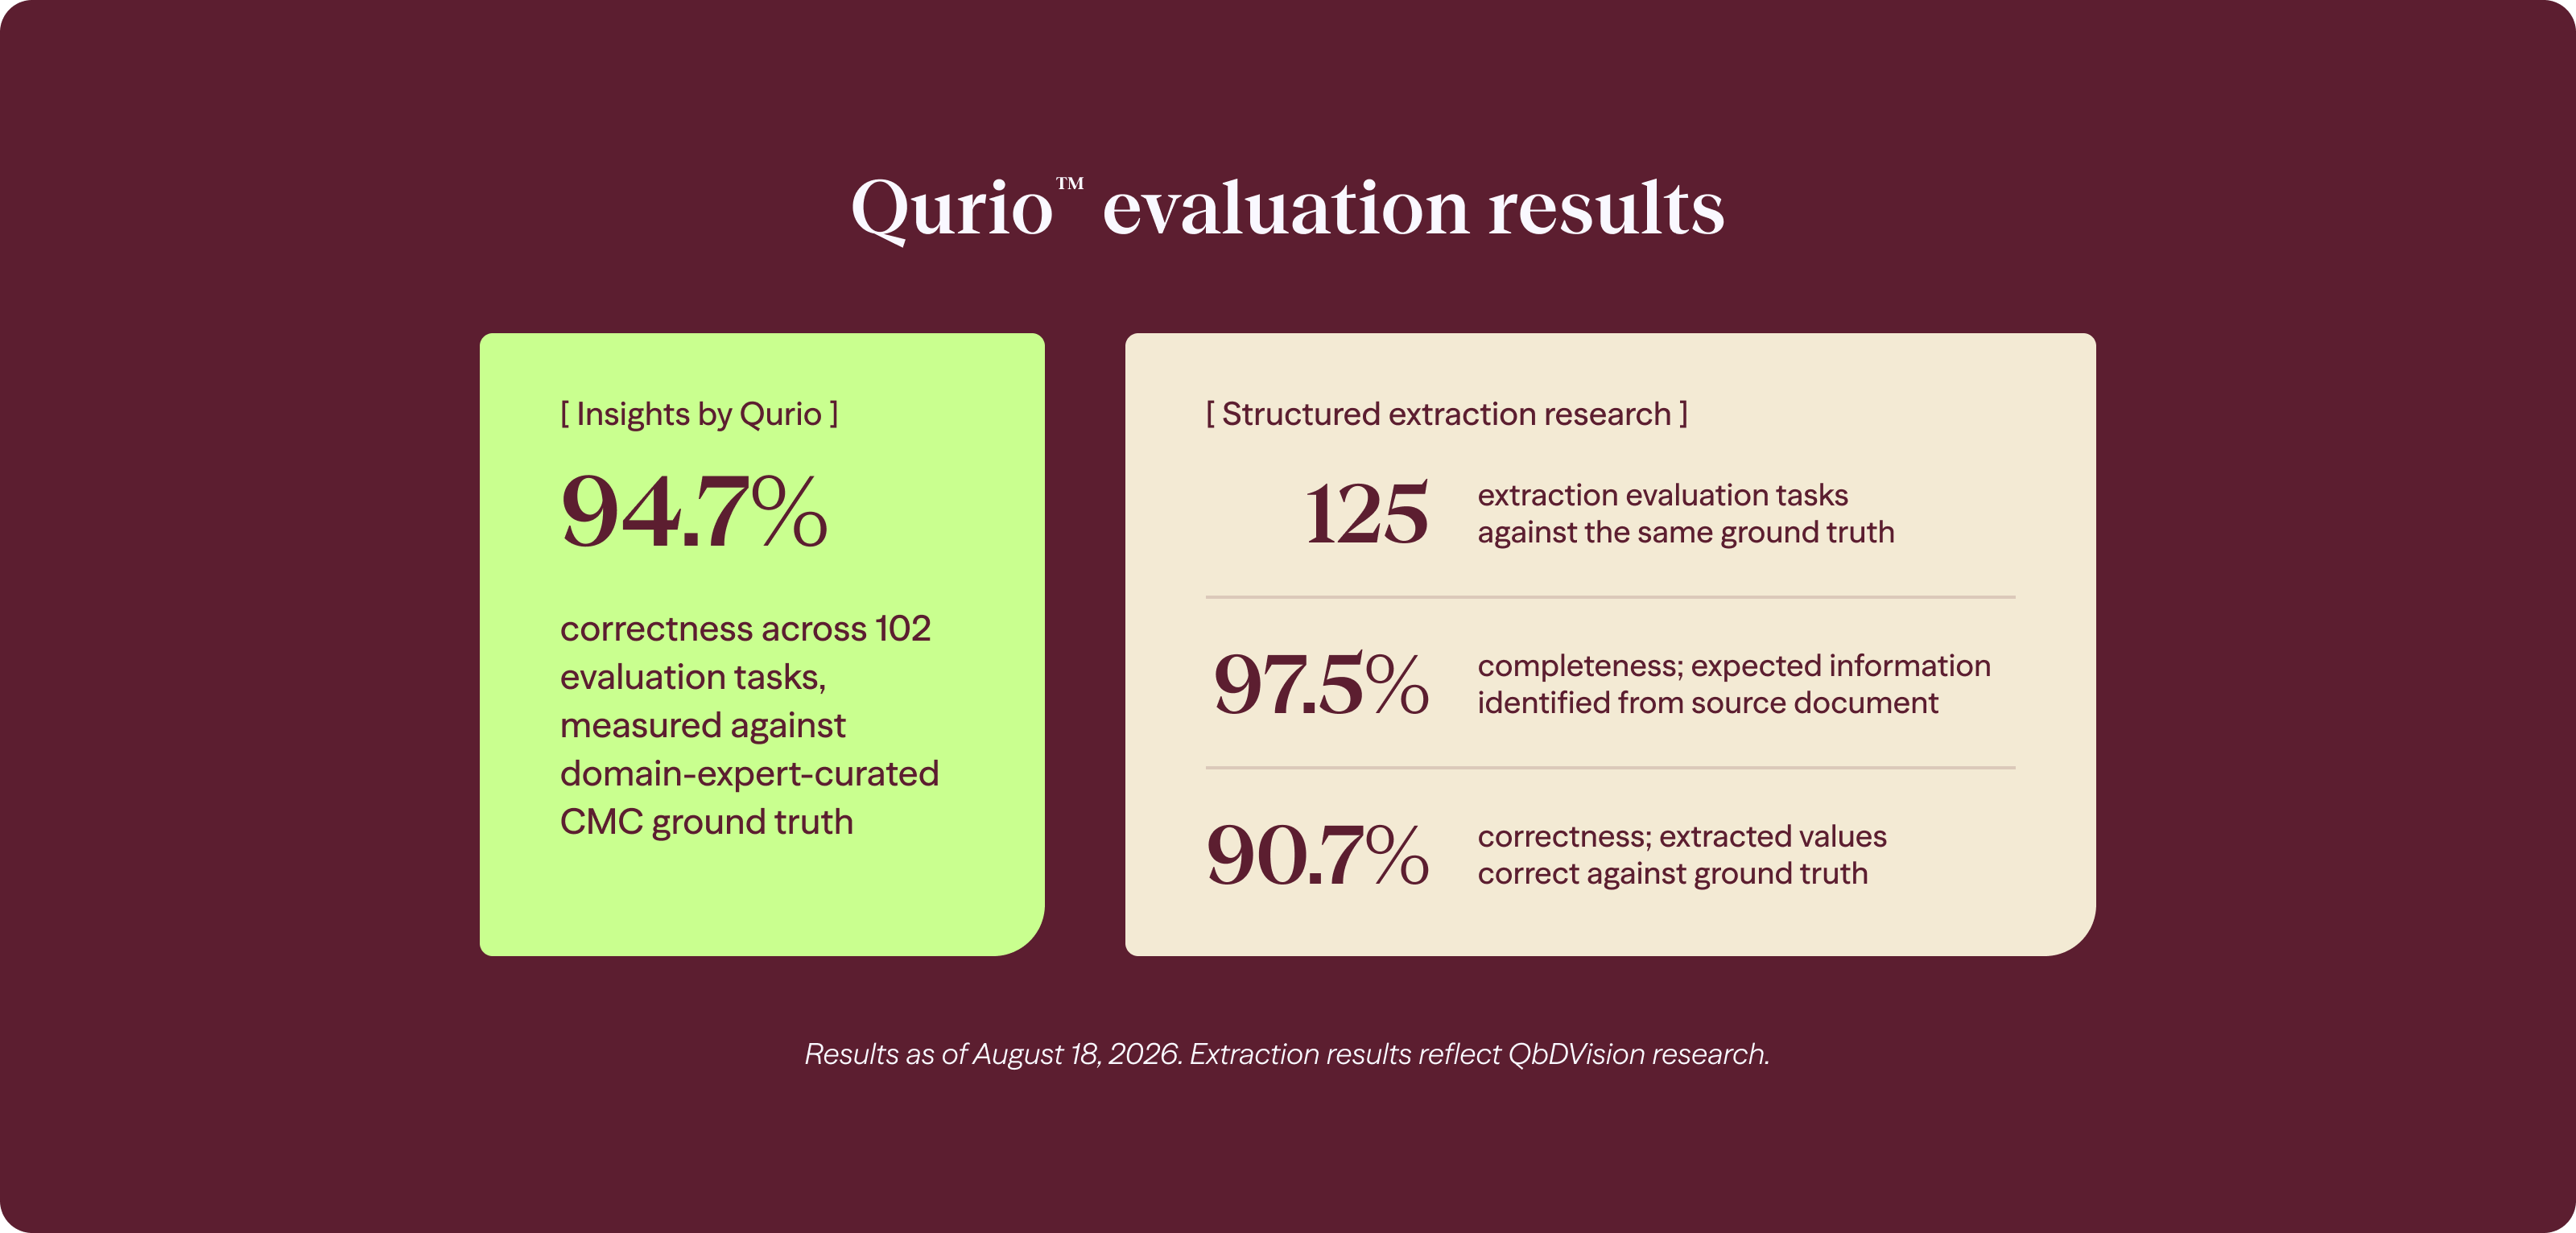
Insights is the second job: the AI answers questions about process history, development rationale, and the relationships between parameters, quality attributes, and the evidence behind them. It is measured on recall, accuracy, completeness, and reasoning. Here the gap is between "studies that support this range" and "all studies that support this range," so recall and completeness carry the most weight. This is the track that catches our MSAT lead's problem. Graded on correctness alone, the list of three correct studies scores 100%. Graded for completeness against expert-curated ground truth, it scores 43%, and it fails. For a tech transfer decision, finding 80% of the supporting evidence can be more dangerous than finding none, because it creates false confidence.
Two more dimensions apply across both tracks: regulatory compliance, meaning whether outputs meet health authority expectations for data integrity, and stress resilience, meaning how the system holds up against OCR errors, handwriting, outdated formats, and missing data. Real documents are rarely as clean as the demo.
We hold our own AI to this standard. Insights by Qurio is evaluated against domain-expert-curated CMC ground truth, and so is our structured extraction research. In the results below, correctness is how we score accuracy against that ground truth.
What We Learned
Building that benchmark confirmed something the MSAT lead's question already hints at: a single rolled-up accuracy score hides more than it shows.
CMC spans several specialties. Materials, equipment, unit operations, process steps, and process parameters each belong to different experts, carry different complexity, and fail in different ways. A model that performs strongly on material extraction may perform very differently on process parameters, and an aggregate score hides exactly where intervention is needed.
That is why QbDVision uses different AI models for different CMC tasks, and why measurement decides which model handles which task. It also answers a question customers ask us often: which AI model do you use? The one that measures best on the task in front of it, verified against ground truth rather than assumed from a leaderboard.
Measure Before You Deploy
Look again at the order of events in that opening demo: deploy, hope it works, find problems, patch, and eventually, maybe, arrive at a system people trust. Measurement reverses that order.
CMC teams already know this sequence from drug development. Quality by design begins with the quality target product profile, defined before the process is designed, and the rest of development is built to meet it. AI in CMC warrants the same discipline: define what good looks like for the intended use, measure against it, and deploy once the evidence is in.
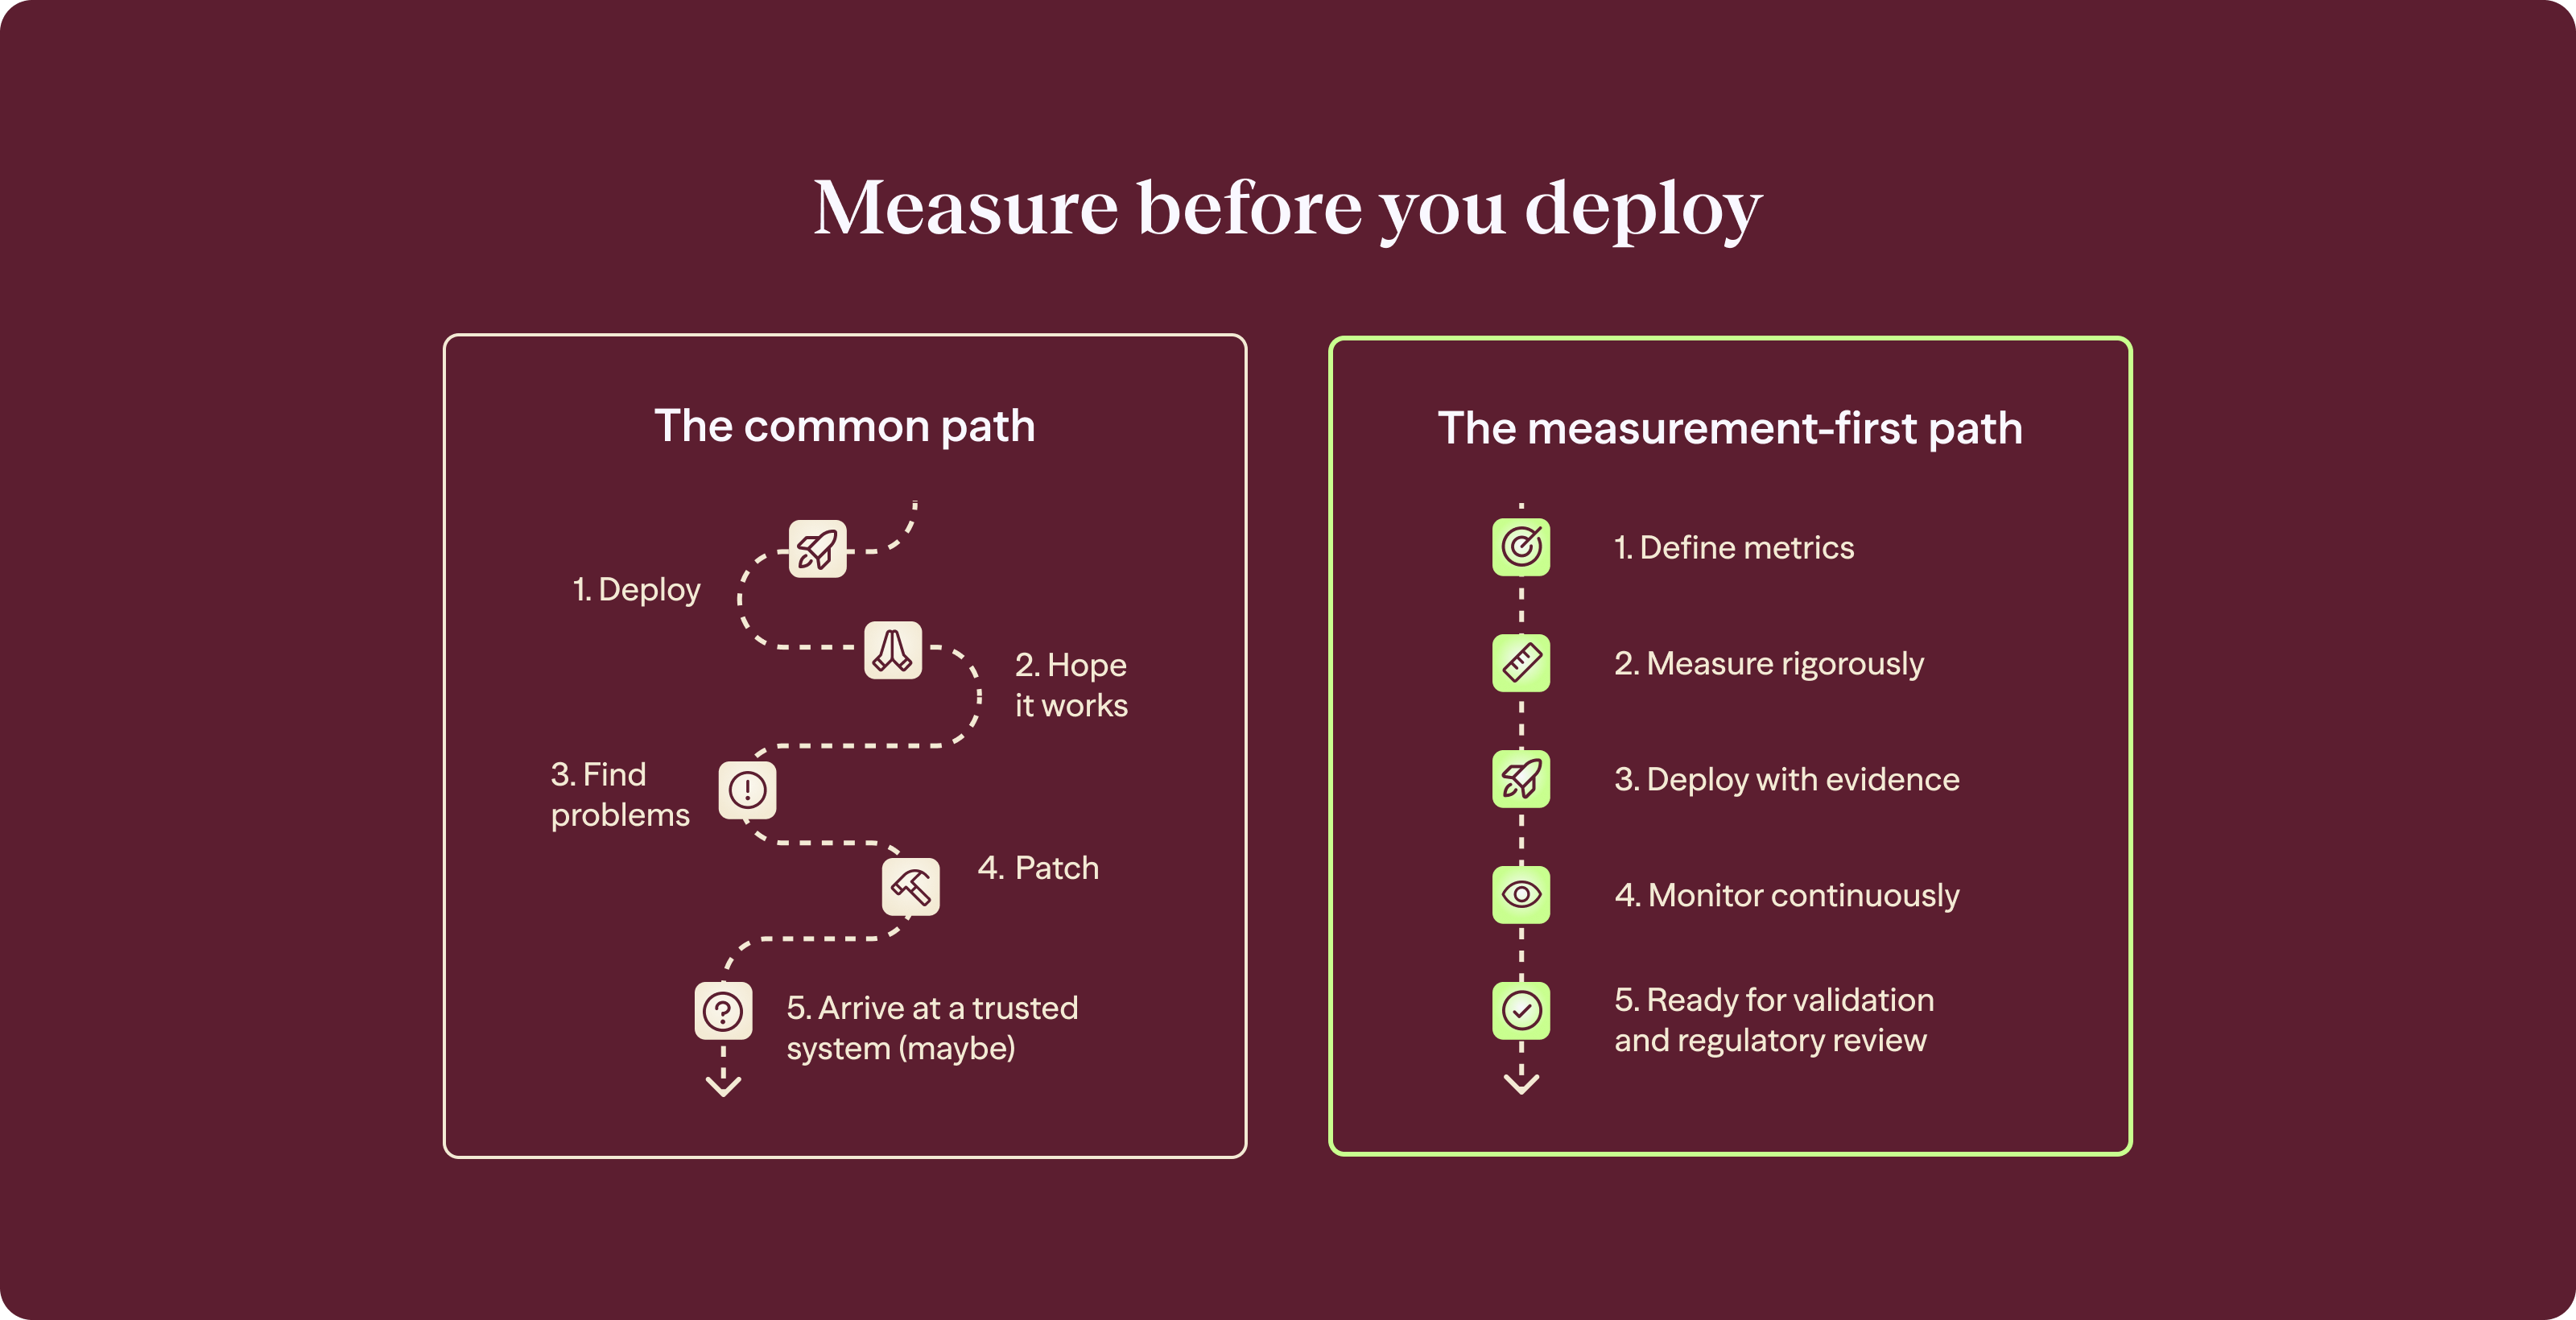
Measuring first puts the work up front and avoids the rework. It also removes the most expensive failure mode: a system that looks like it's working when it isn't. If you're evaluating AI in CMC, three steps make that concrete.
Ask any AI provider, including us, for CMC-specific evidence. General benchmarks such as MMLU (Massive Multitask Language Understanding), a multiple-choice test of general knowledge across 57 academic and professional subjects, will not answer the question. Ask for performance on your document types, your data structures, and your regulatory requirements; performance under stress, such as OCR errors and missing data; and traceability evidence. A provider that cannot share this evidence has not yet shown its system is credible for CMC.
Define acceptance criteria before you deploy. Assess the risk of each use case, since high-risk uses demand stricter criteria, and document what "good enough" means for each workflow. That record becomes part of your credibility and validation evidence.
Keep measuring. Performance drifts, and new document formats appear. Treat the AI the way you would treat a commercial process under continued process verification: track whether accuracy holds steady, when people override the AI and why, and whether the system is reducing cycle time as expected. When performance shifts, ask the questions you would ask of any process trend. Is there an explainable cause? Is the measurement method precise enough to detect the change? Is the system still fit for its intended use?
Back to the Original Question
Picture the same tech transfer with measurement in place. The system still has to find seven records across years of development work. This time, Caroline knows how it performs on completeness for exactly this kind of question, what threshold her team set before it went live, and what evidence sits behind that number. Because the range, the quality attribute it protects, and the studies behind it are connected as structured data, the answer arrives with its sources, and any gaps are visible. She knows how far to trust the list, and when to ask for more.
The timing matters. Regulatory expectations for AI credibility are taking shape, failed pilots are expensive, and boards are asking for evidence before they fund. Teams that define how they measure AI in CMC now will be ready as those expectations firm up.
Trust in AI for CMC is earned the same way trust in a process is: defined criteria, evidence, and continued measurement.
Senior Product Manager
Jack Morel
Jack is a synthesist and former research scientist. As a product manager, they bring together the best parts of software, hardware, and biology to bring therapies to patients faster. In the past they've worked in product management at SaaS and CDMO companies, led solution engineering for F500 biotech and pharma, and developed laboratory automation late stage drug development.
Explore the world of Digital CMC